
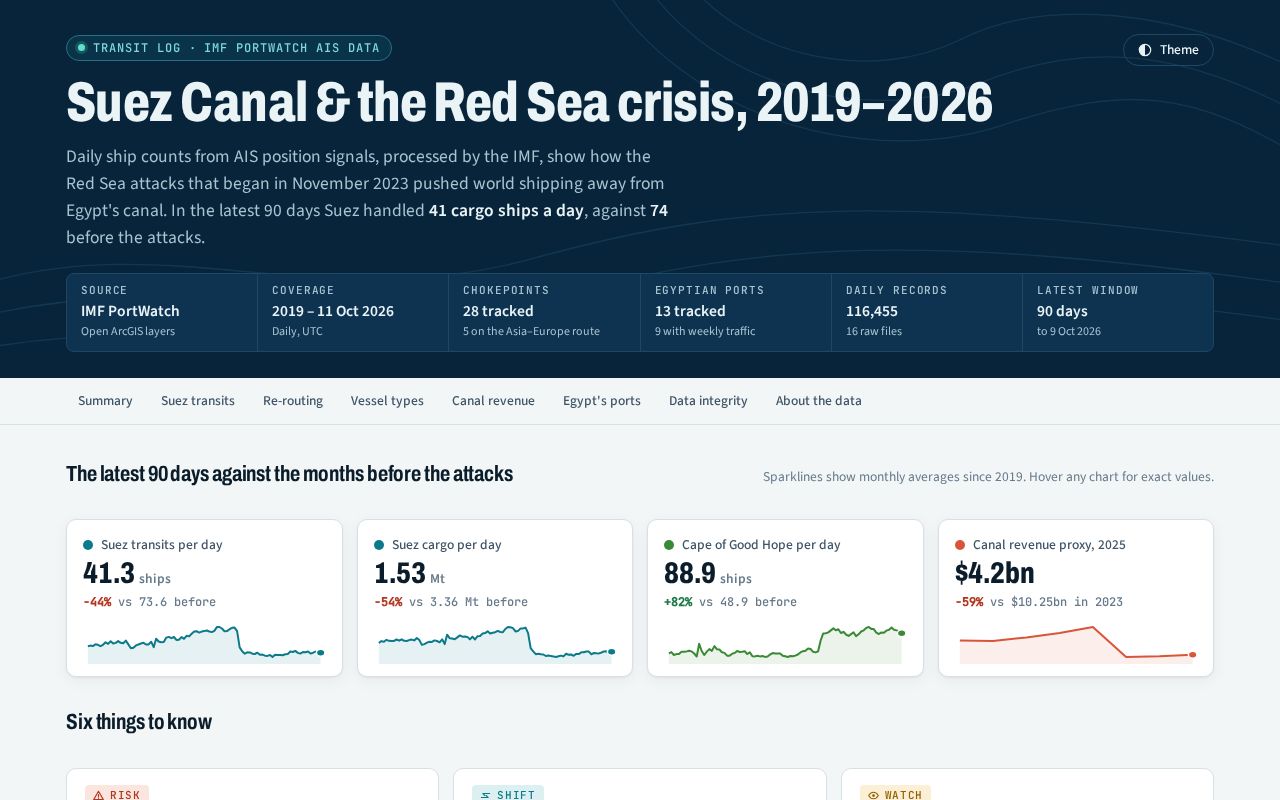
Suez Portwatch
Suez Canal & Red Sea disruption 2019-2026 from IMF PortWatch AIS data: Python + DuckDB bronze/silver/gold pipeline, SQL analyses, data-quality tests and an interactive dashboard.
BitsExplorer finds what people are building with AI, every day. See today's picks →
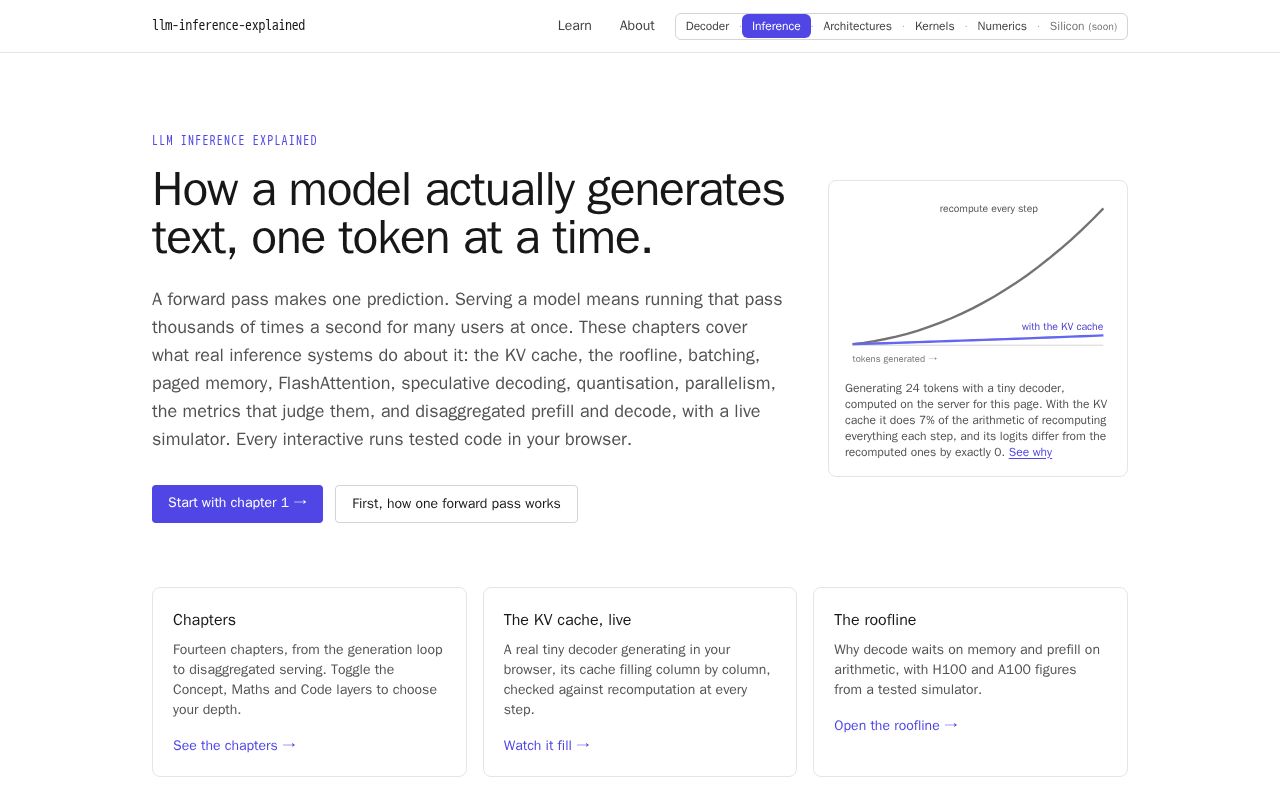
Interactive explainer of real LLM inference: KV cache, roofline, batching, paging, FlashAttention, speculative decoding, quantisation, parallelism and serving metrics. Companion to the Transformer Decoder Explainer.
Description excerpted from the original listing, which is linked below.
Suez Canal & Red Sea disruption 2019-2026 from IMF PortWatch AIS data: Python + DuckDB bronze/silver/gold pipeline, SQL analyses, data-quality tests and an interactive dashboard.
BLOOM - From Cherry to Cup: a three-episode 3D animated fairy tale about coffee, made in Blender, with its website (COMP5415, University of Sydney).
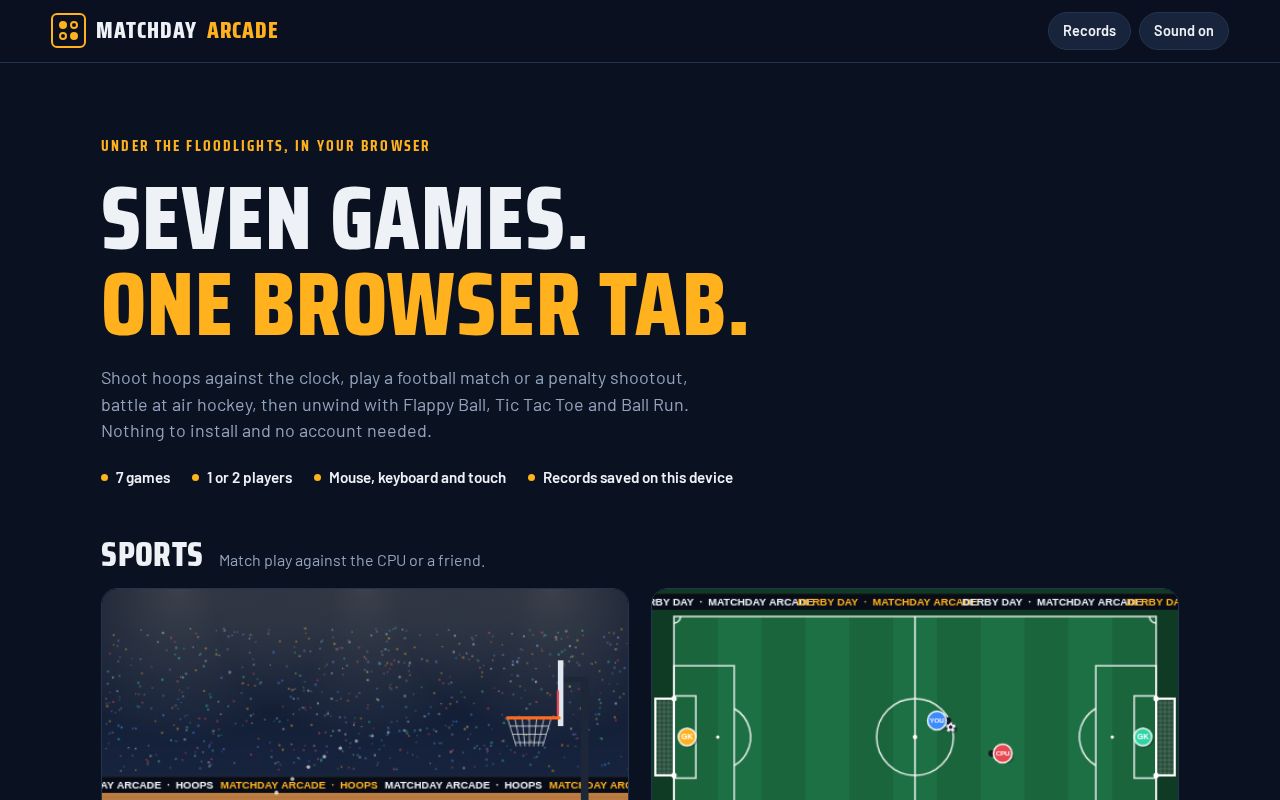
Four browser sports games: basketball, football, penalties and air hockey
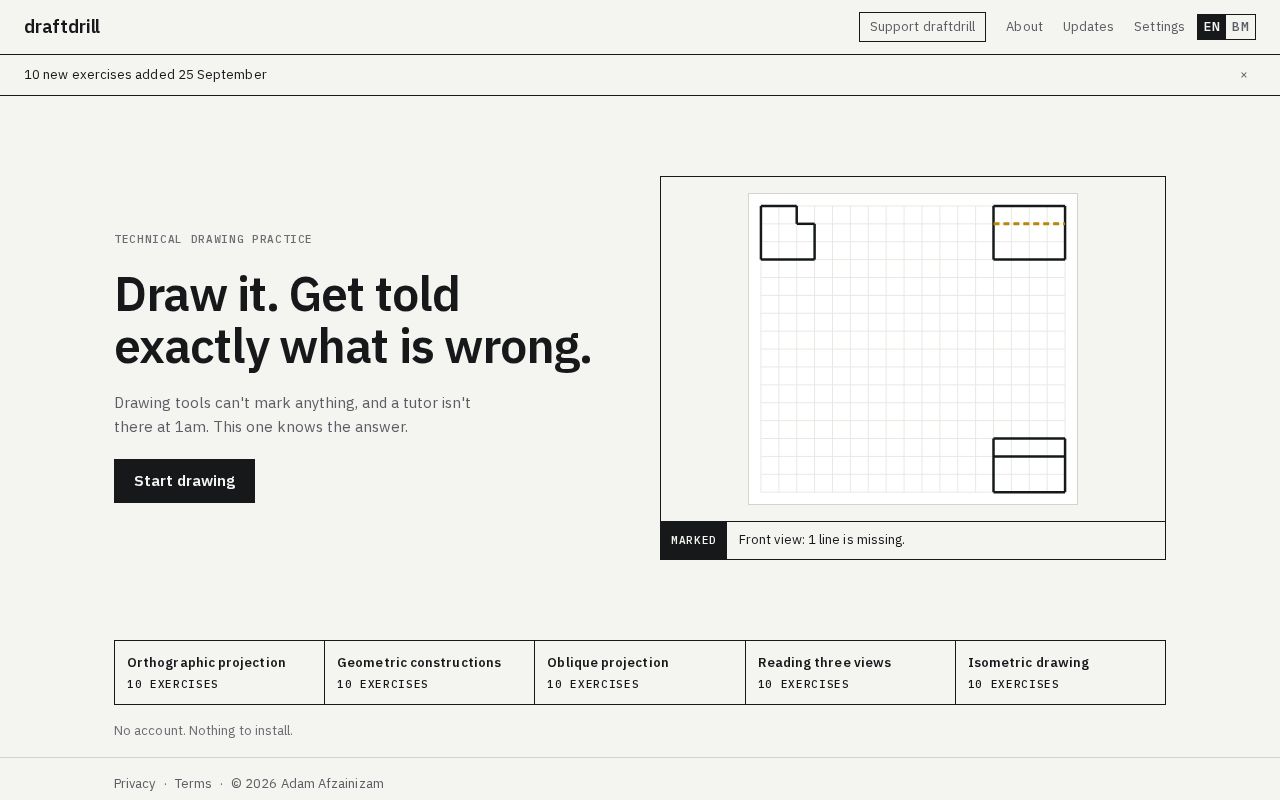
Showcase for draftdrill: practise technical drawing and get marked. Diagrams, launch video and design notes (source is private).
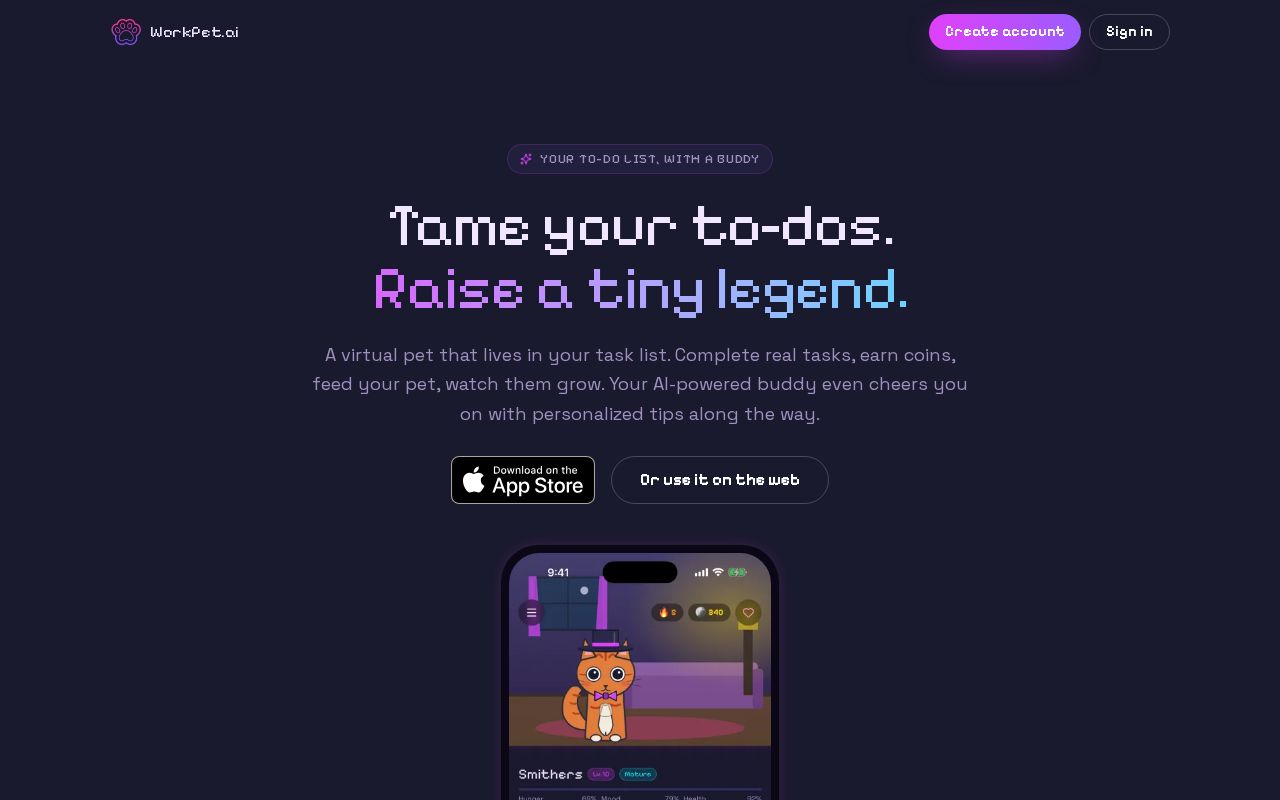
A virtual pet that lives in your task list. Complete real tasks, earn coins, and raise an AI-powered buddy who cheers you on. Free.
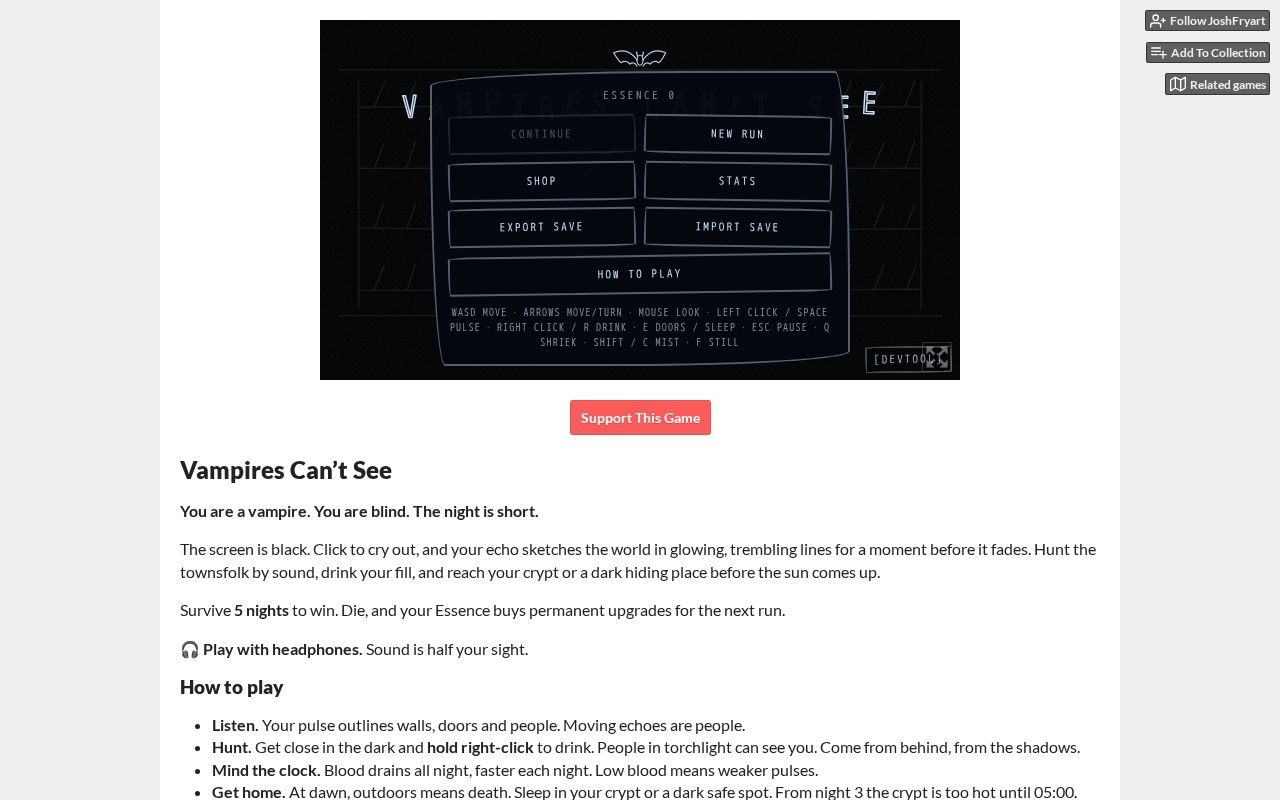
You are a Vampire. You are blind. Echolocate your victims, and survive the night!
PHP client for the Bullhorn REST API (staffing and recruitment CRM): OAuth login, a shared session that survives concurrent requests, entity, search and file helpers, and a Laravel integration with facade, encrypted session cache and Http::fake() support.
Best SEO Services for Google, AI Search, and Revenue Growth We help your business rank higher on Google and get recommended by ChatGPT, Perplexity and Google AI Overviews — turning search into qualified leads and measurable revenue.
Every Monday: how many projects were built with AI that week, which tools built them, where they came from, and the week's picks.
Read the latest week