
Blobble
A chat where words bring little things to life
BitsExplorer finds what people are building with AI, every day. See today's picks →
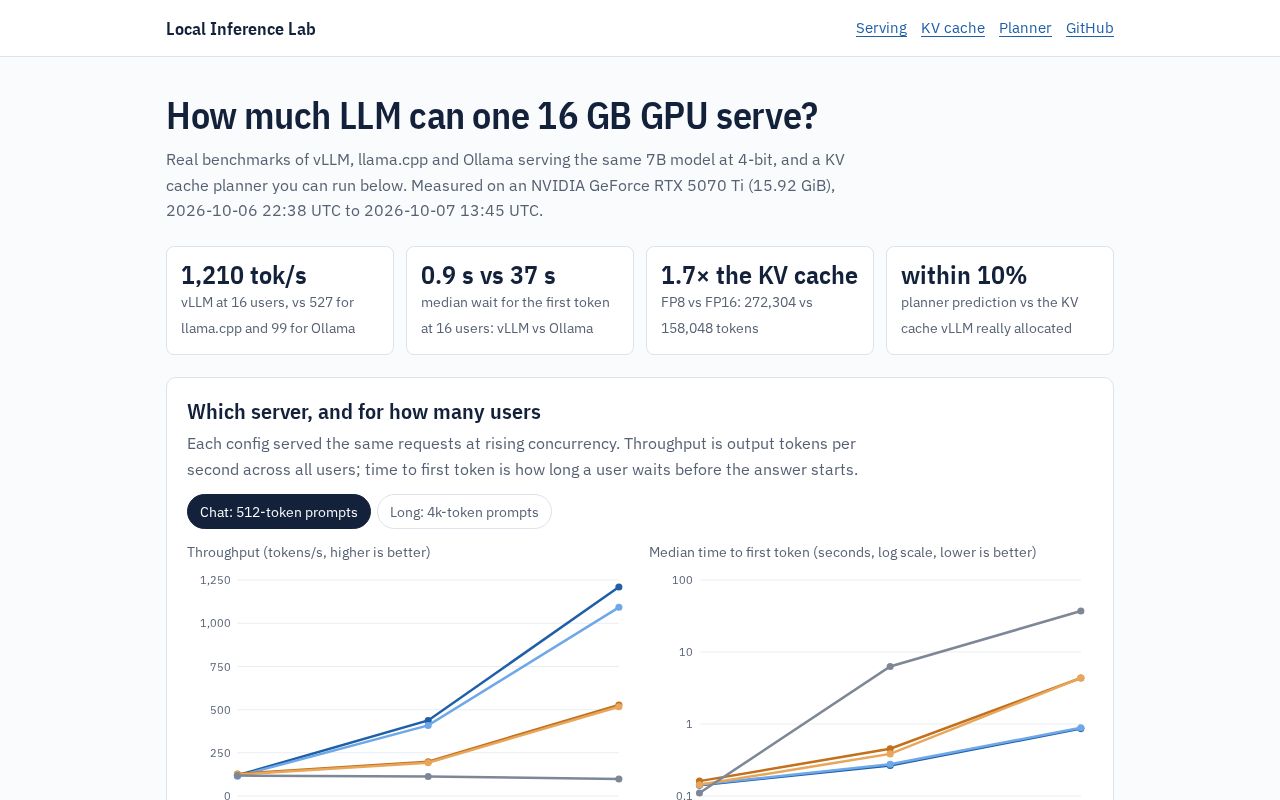
Serve, size and benchmark open LLMs on one 16 GB GPU: vLLM vs llama.cpp vs Ollama, KV cache and offload planning, MCP server
Description excerpted from the original listing, which is linked below.
A chat where words bring little things to life
Home page, privacy policy and terms of service for mbgapp, a personal Google Drive copy tool
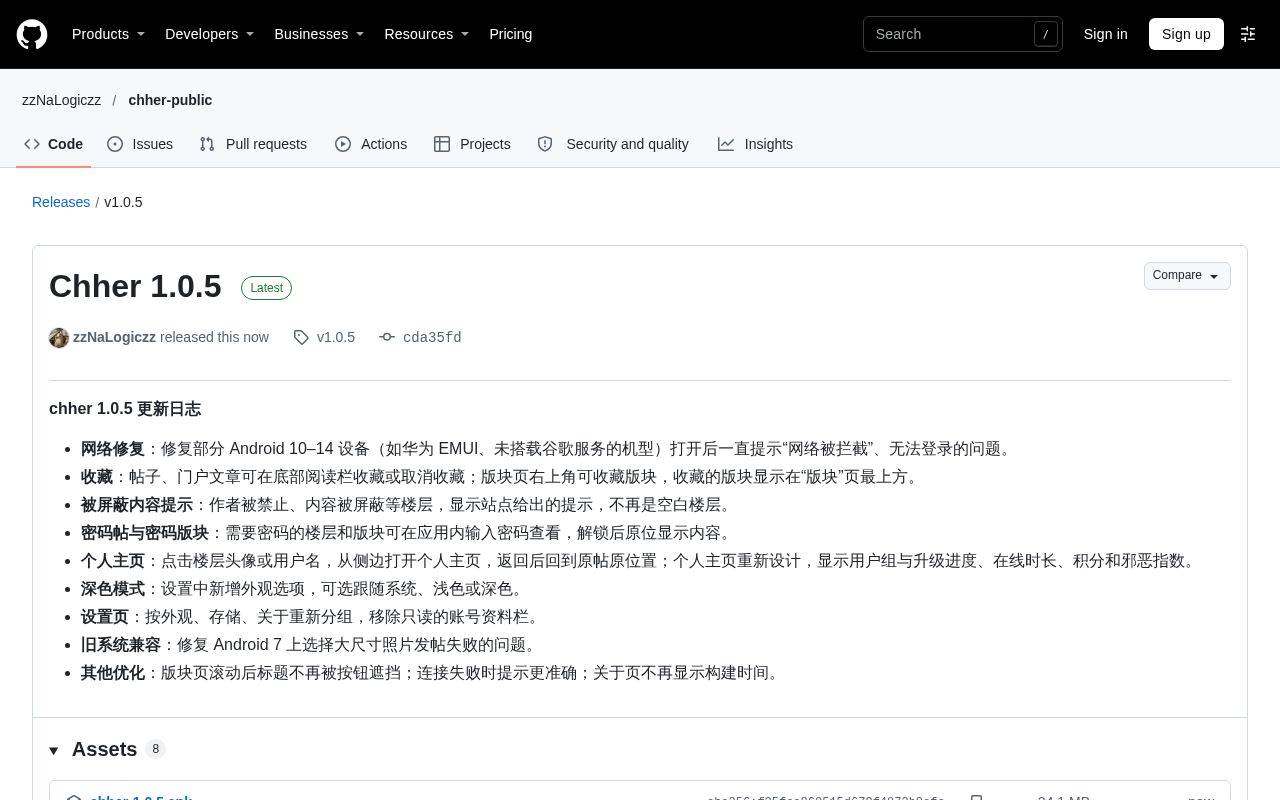
Chiphell 非官方 Android 客户端;源码可用,采用 PolyForm Noncommercial 1.0.0 许可
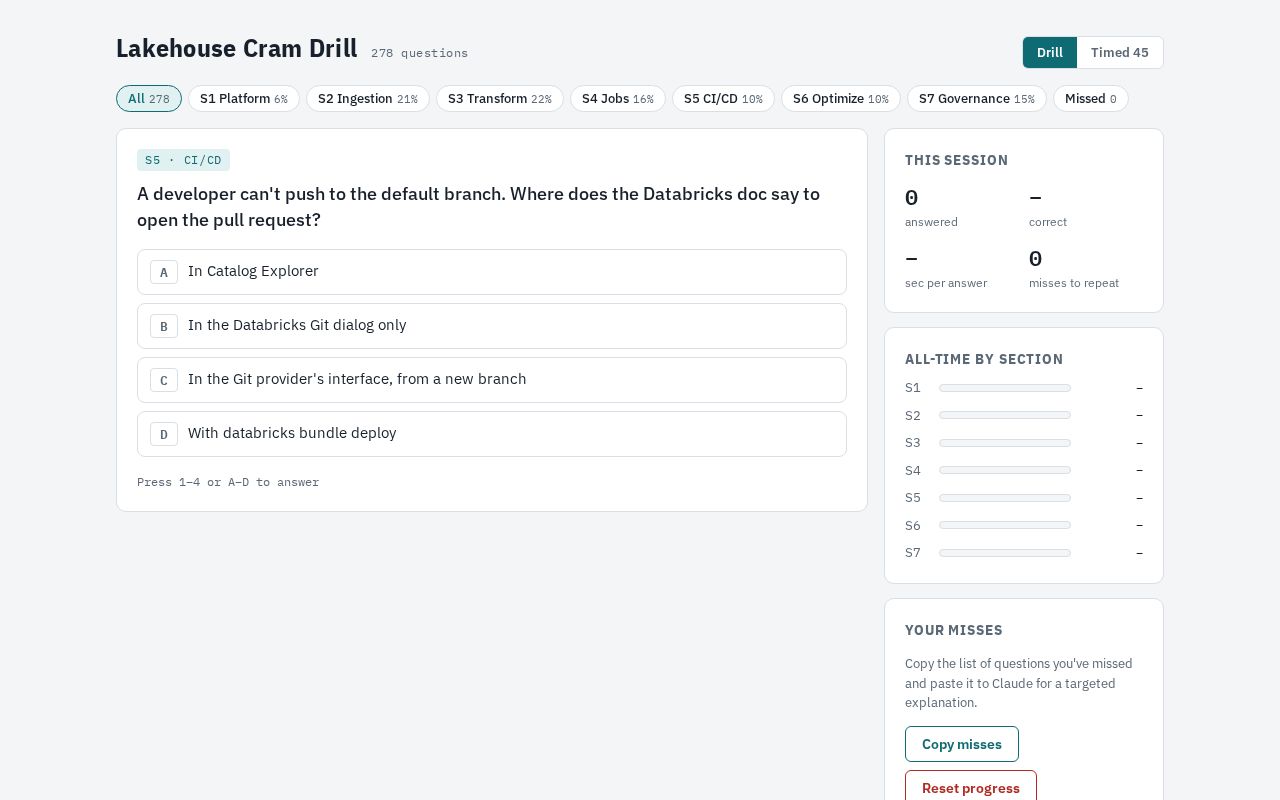
A pratice portal for preparing for the Databricks Data Engineer Associate Certification. Questions generated by Claude, so 100% accuracy is not guaranteed.
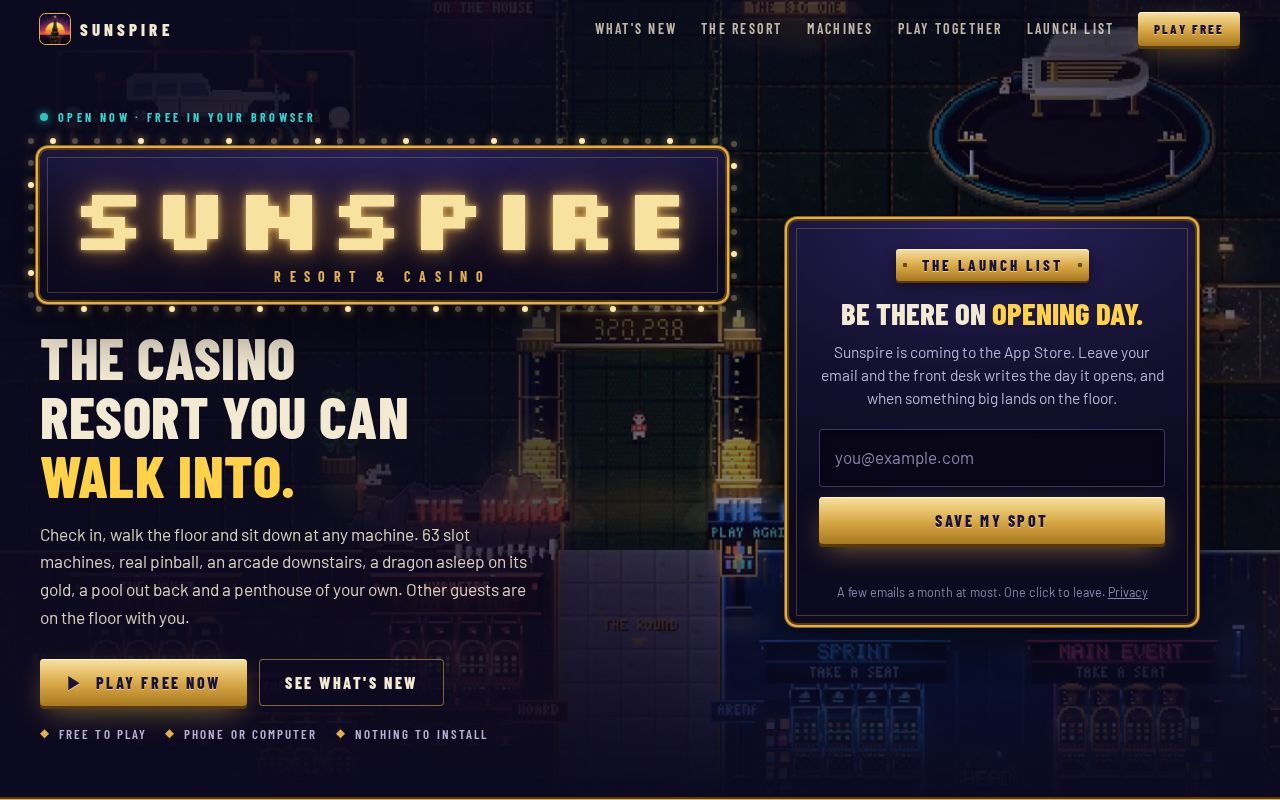
A pixel casino resort you walk around in. 63 slot machines, an arcade downstairs, real pinball, a pool, a penthouse and other players on the floor. Play free in your browser.
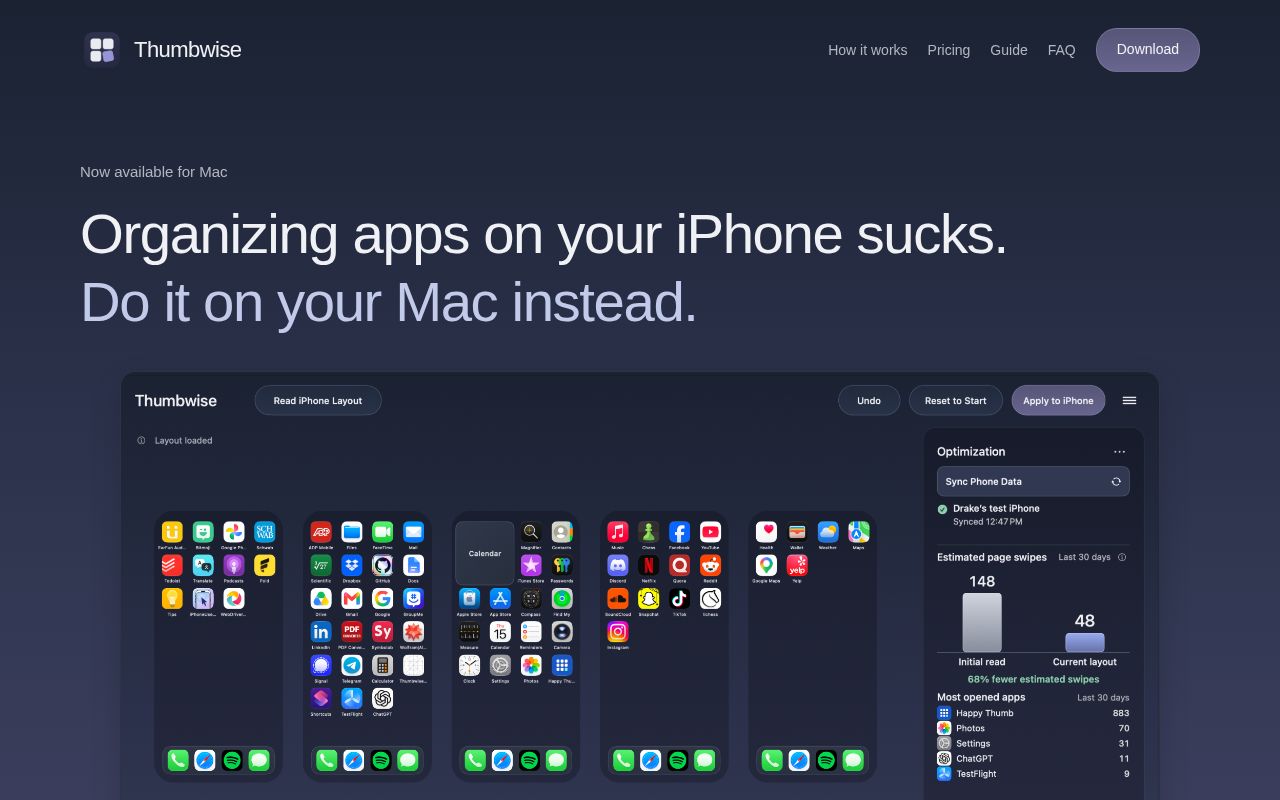
Organize your iPhone apps on your Mac with Thumbwise. Customize your Home Screen layout, then apply it to your iPhone. Free to download; $14.99 once to unlock Apply.
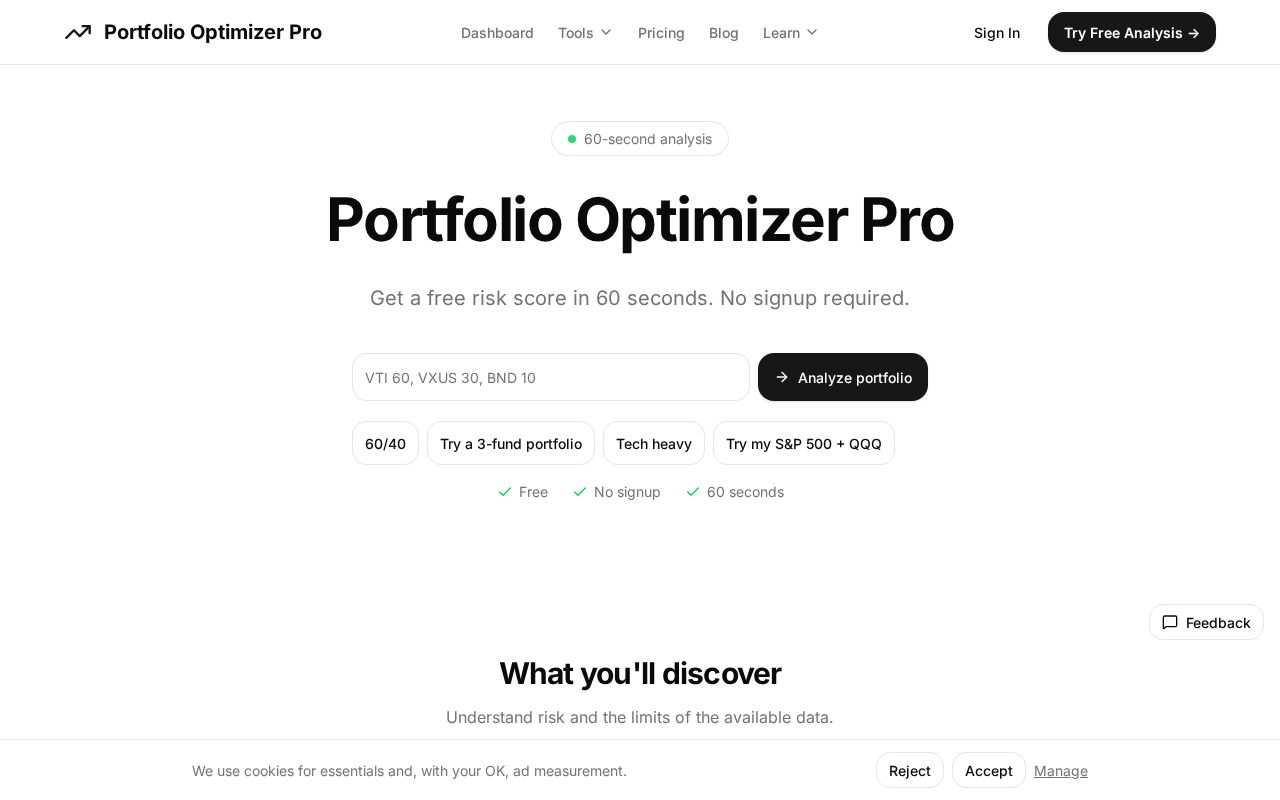
Analyze holdings without signup. Free risk grade, holding stats, correlation heatmap and efficient frontier showing your portfolio position.
A live chart of your repo's stars that updates itself, labels your spikes and matches light and dark mode. From $1/month.
Every Monday: how many projects were built with AI that week, which tools built them, where they came from, and the week's picks.
Read the latest week