
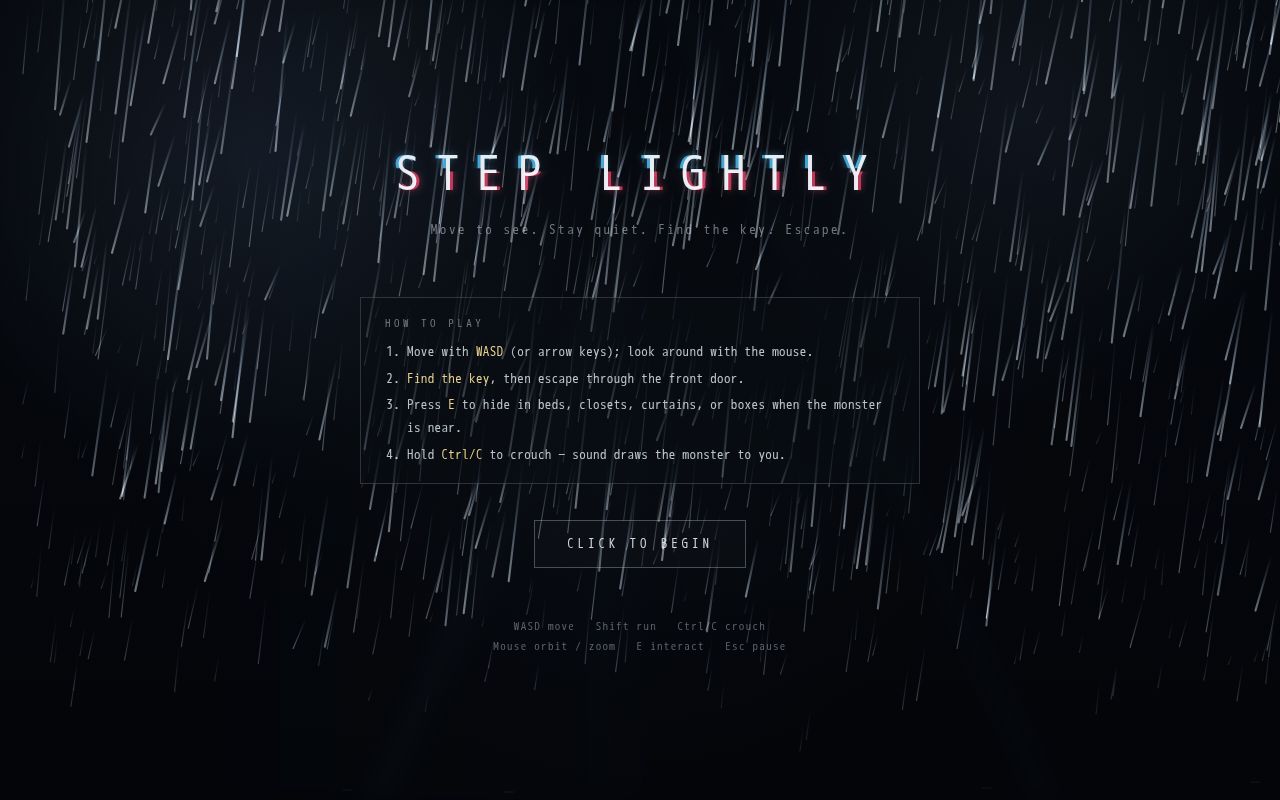
Step Lightly
Sneak through a dark ranch house where every footstep lights your way and alerts a monster
BitsExplorer finds what people are building with AI, every day. See today's picks →
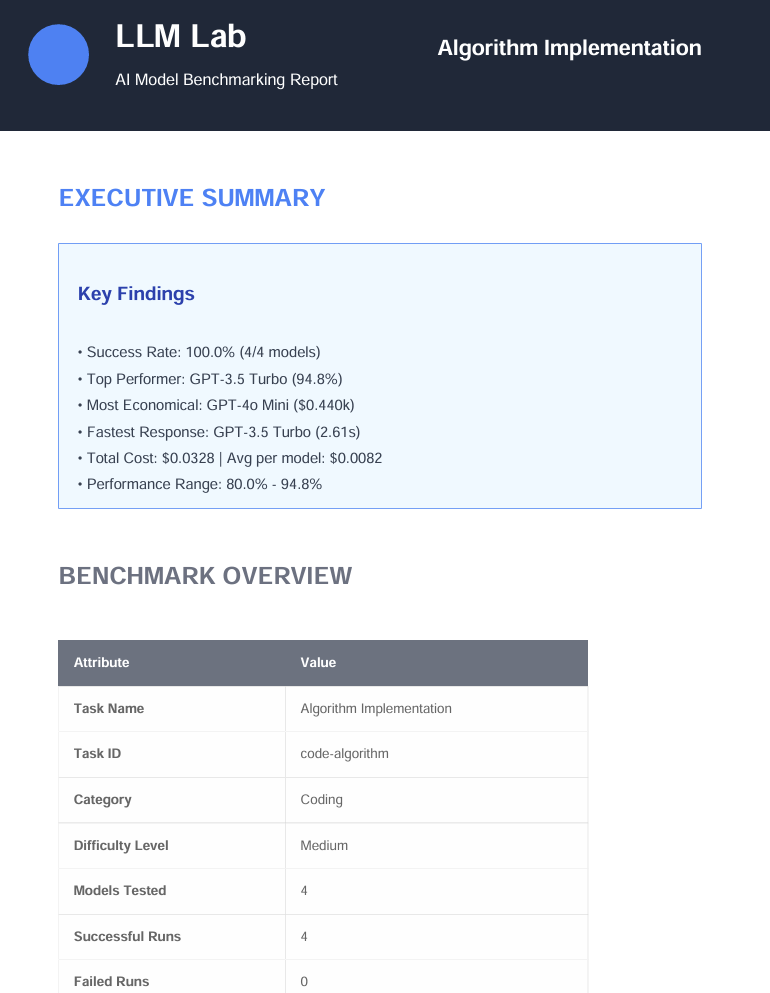
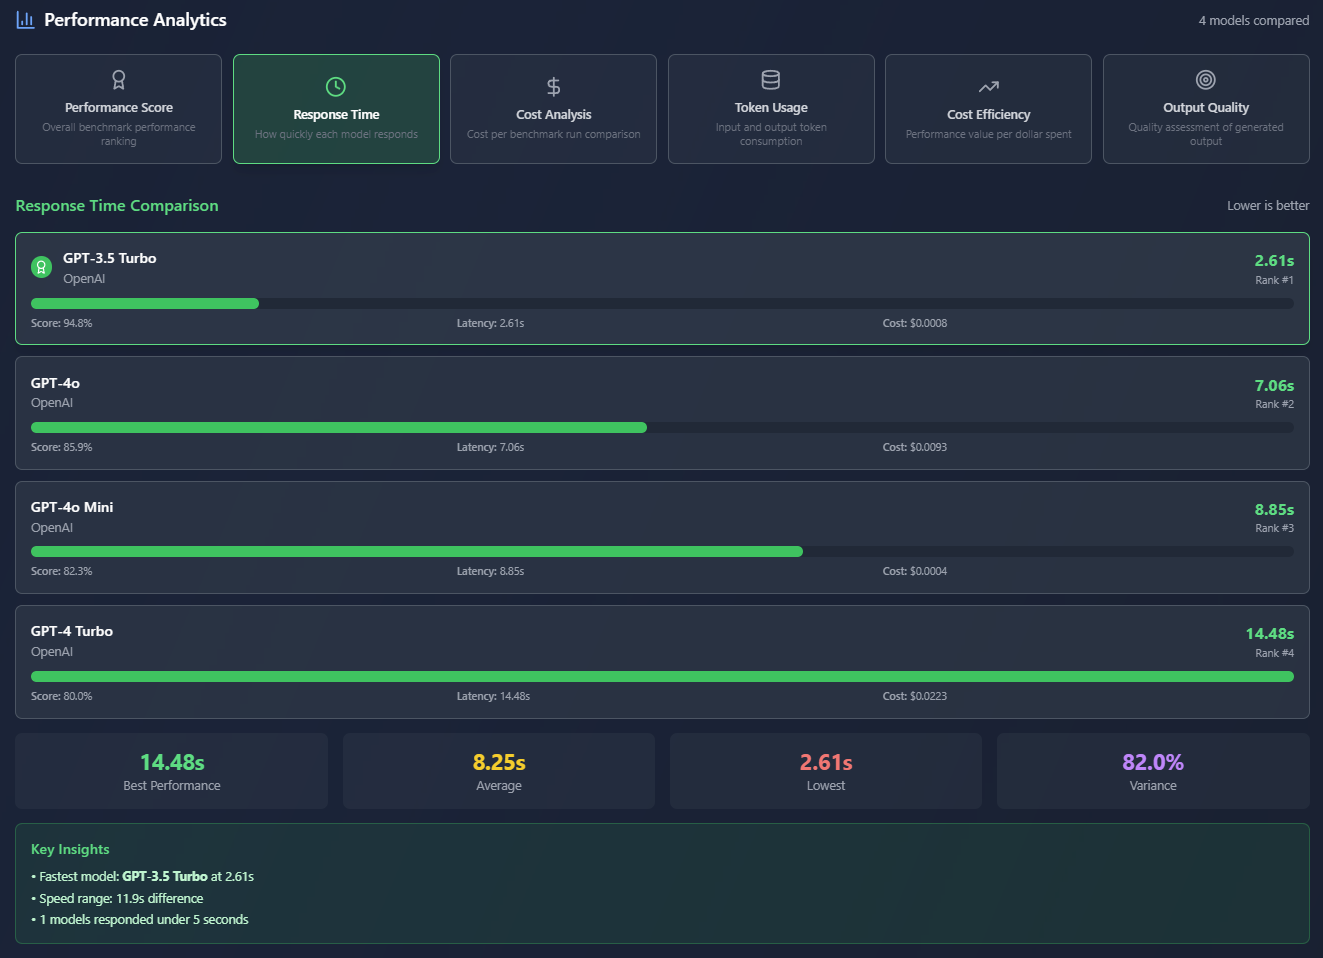
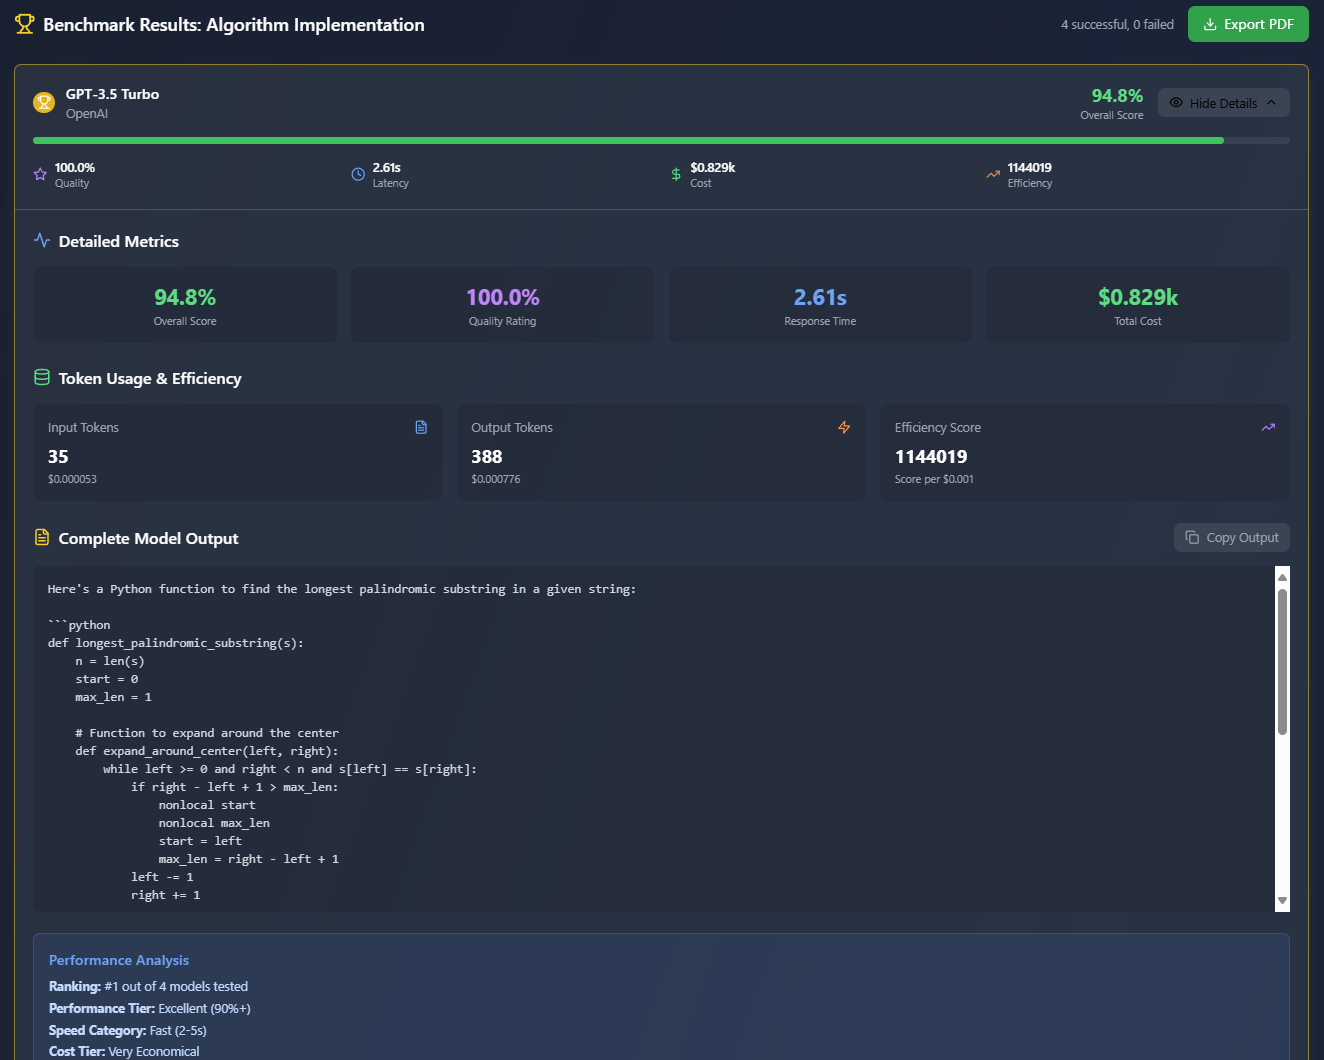
Perform Benchmark Testing and generate Reports for various Large Language Models from OpenAI, Anthropic, and others.
id="app-details-left"> Inspiration There are many large language models to choose from. Each one has pros, cons, costs, and other considerations. I wanted a way to quickly evaluate the best model for a particular task and report on the outcomes. What it does Select one or multiple models from the major companies, and select a pre-defined or custom Benchmark Task. Run the evaluation to generate a UI and PDF report that ranks each model in various categories. View the inputs, outputs, costs, etc for each model. How we built it Vite PWA with Bolt.new. Challenges we ran into Securely managing the…
Description excerpted from the original listing, which is linked below.
Sneak through a dark ranch house where every footstep lights your way and alerts a monster
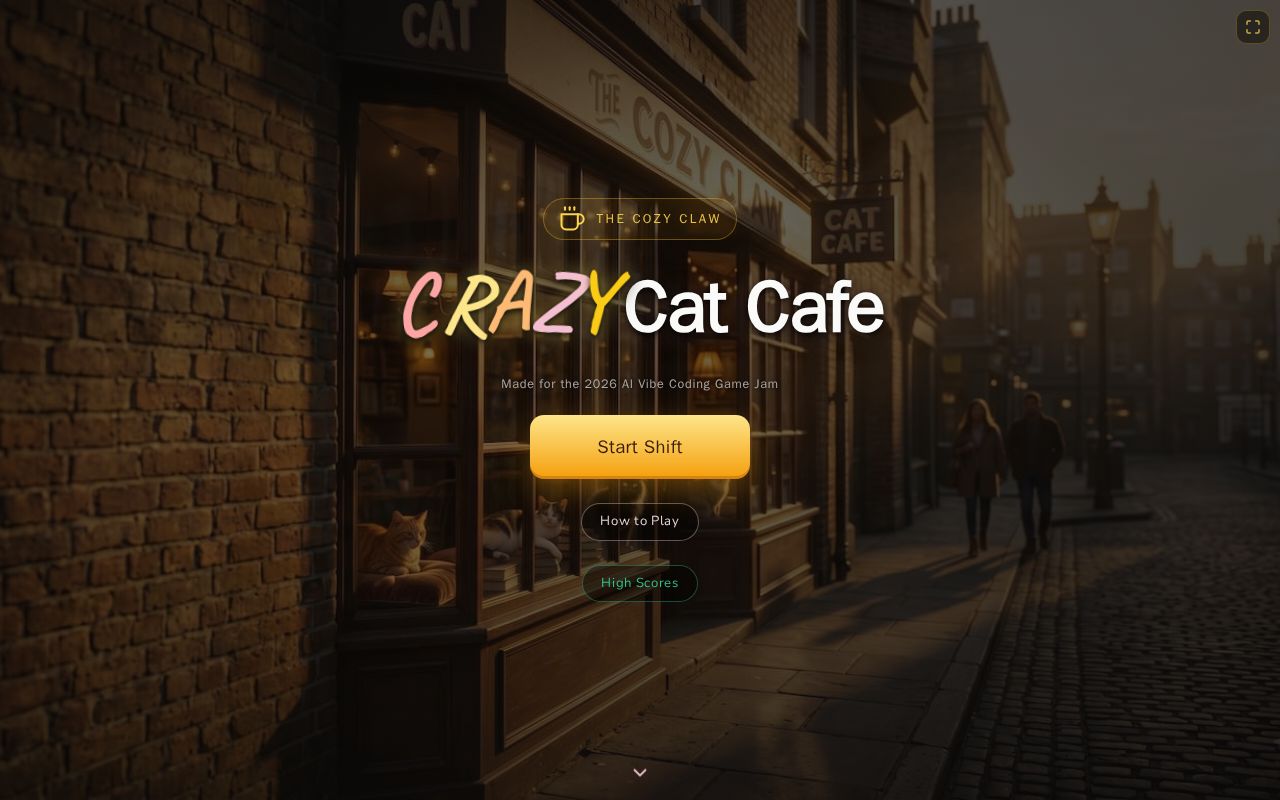
Run a cozy cat cafe while the cats keep knocking your mugs off the counter
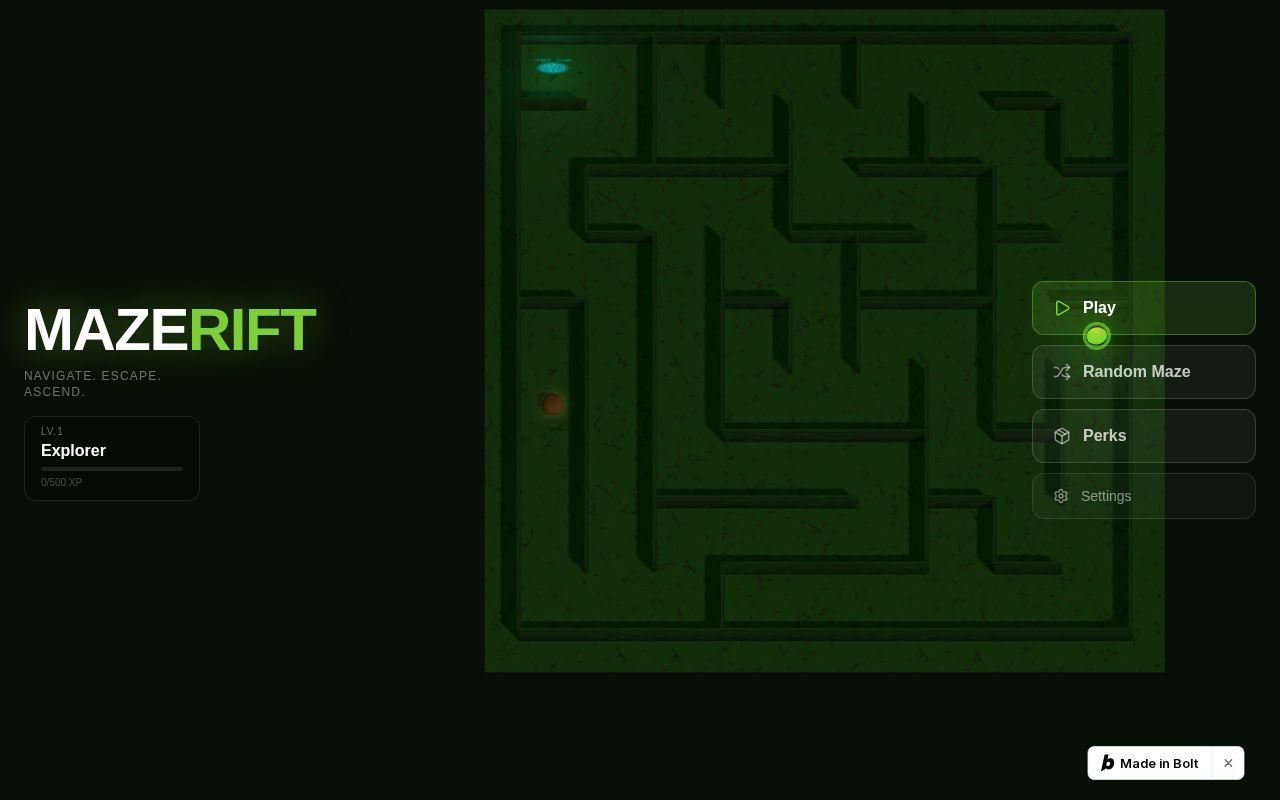
Roll through mazes, collect perks, and race through increasingly strange worlds.
Orbit a star and bend photon beams through gravity to destroy enemy waves
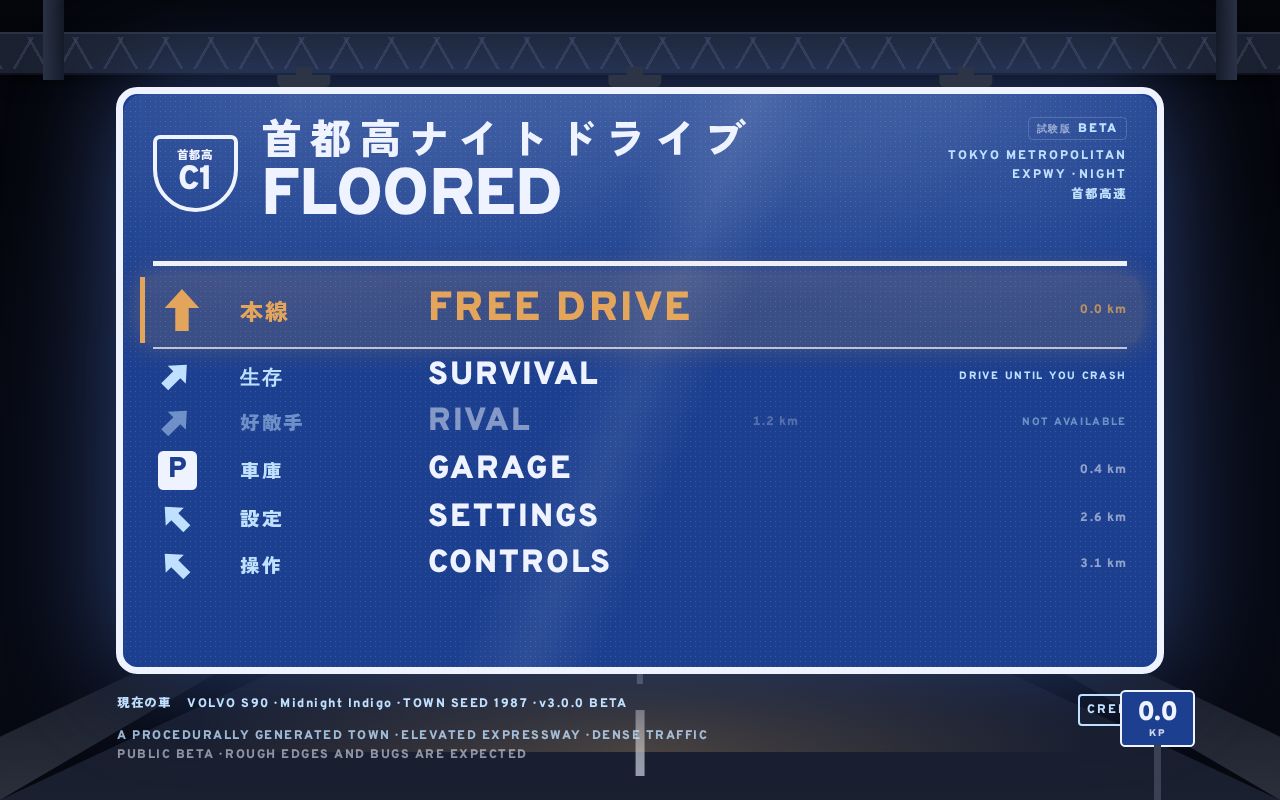
Night driving through a procedurally generated Japanese town and its elevated expressway. Sim-grade tire physics, dense AI traffic, rain, neon.
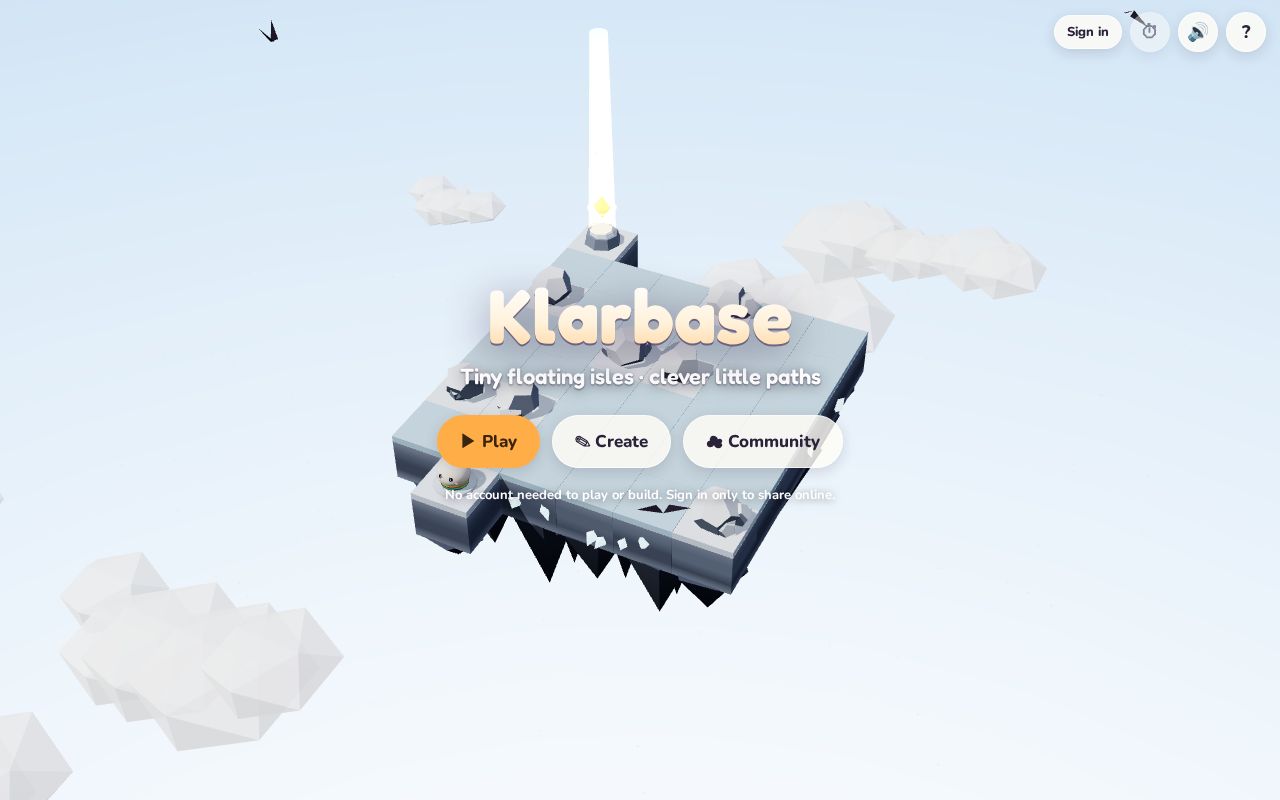
A cozy puzzle game of floating isles. Play 24 hand-made isles, build your own, and share them.
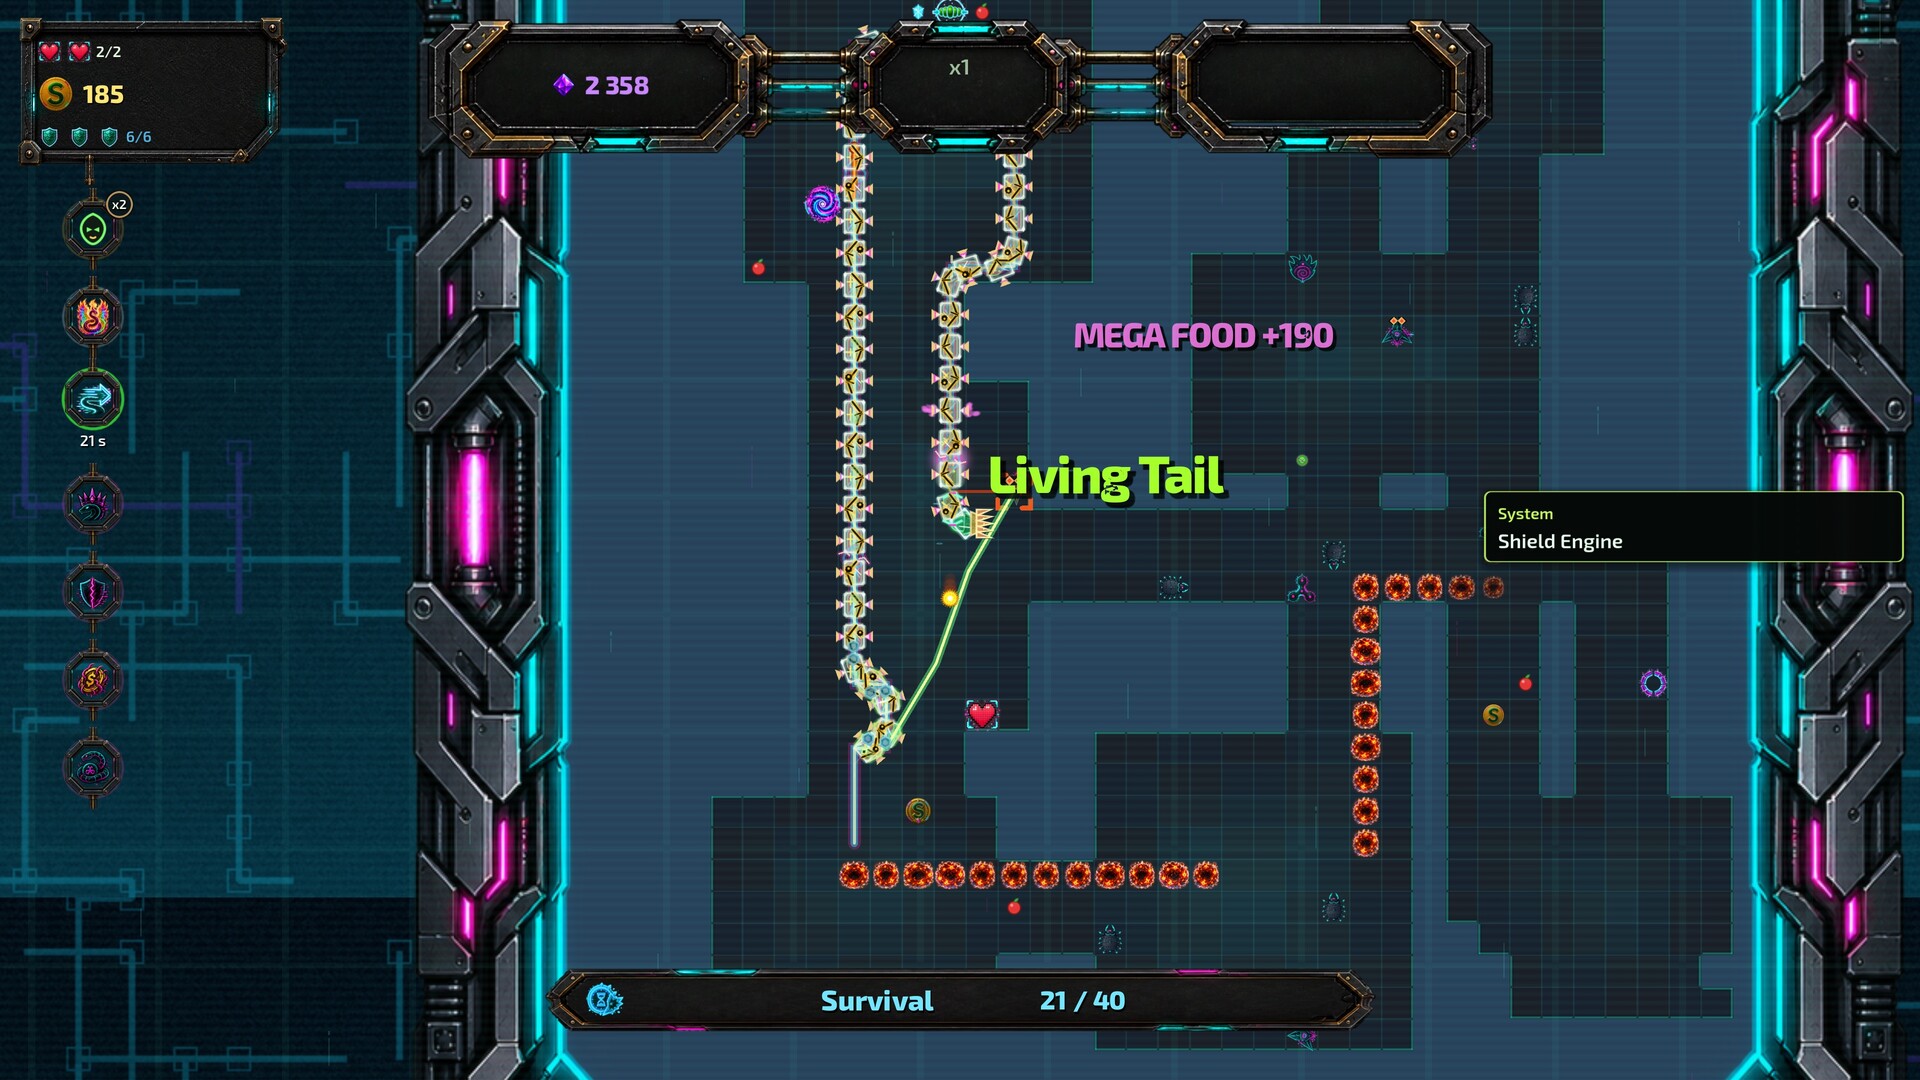
There is no tutorial. And there won't be. I believe in you. I couldn't escape the Grid. Maybe you can. You are snake who eats apples. j/k You want to escape the grid loop. BUT the LOOP wants to keep You in.
Open-source code of the DeDT project: a blockchain-powered decentralized Digital Twins platform (DAO collaboration, big data flows, IP-NFT fundraising, trustworthy predictive analytics). MSCA Fellowship, Masaryk University.
Every Monday: how many projects were built with AI that week, which tools built them, where they came from, and the week's picks.
Read the latest week